A fast API response does not mean a fast file. An image job can be accepted in milliseconds, while the finished file only shows up seconds later. This guide explains how to measure each stage of a request, how to test image, video, and music jobs fairly, and how to set targets your product can actually meet. For a look at how different providers compare, see our model-switching speed comparison.
Public data on this topic is limited. Video speed, music speed, and how many jobs a provider lets you run at once are rarely published, so testing with starter credits yourself is often your best option.
What Latency Means in a Unified Media API
Latency in a unified media API is the time from a user’s request to a file they can actually use. That is a bigger window than the time between sending a request and getting a success response. A quick job ID keeps your app feeling responsive, but it does not mean the image, clip, or track is ready.
For background on how one API can sit in front of several model providers, see our explainer on what a unified AI media API is. For performance work, it helps to split a request into four separate clocks:
- Time to first response: how long the API takes to accept the request.
- Queue wait: how long the job sits before a worker picks it up.
- Generation time: how long the model takes to produce the output.
- Delivery time: how long encoding, quality checks, storage, and the completion notification take.
For a simple image request, the first response and the total time might be close together. For video or music, they usually are not. A provider might hand back a job ID in 300 milliseconds while the finished file takes 90 seconds to arrive.
Public comparisons show why a single average can be misleading. One published test reported image generation times of around 2,400 milliseconds for ModelsLab and fal.ai, compared with about 3,500 milliseconds for OpenAI. Treat numbers like these as a general reference, not a guarantee for your own workload. Model choice, output size, region, current queue load, and startup delays on an idle model (often called “cold starts”) can all change the result, so confirm any published figures before you rely on them.
It also helps to measure what we call accepted-output latency. This clock starts when the user submits a request and ends when the file loads, passes your checks, and is good enough to keep. A result that comes back quickly but needs a second attempt can end up slower overall than a result that took longer the first time.
Good backend timing data lets your team label each stage of a job without exposing private infrastructure details. That way, when a customer reports a slow job, you can tell right away whether it was stuck in the queue or genuinely took longer to generate.
Key takeaway: Track acceptance, queue wait, generation, delivery, and accepted-output latency as five separate measurements, not one number.
How an AI Media Request Moves Through the Stack
A unified media API adds a routing and job-management layer between your app and the underlying model. That layer adds a small amount of time, but in exchange it gives every media type the same sign-in process, job format, notification setup, and billing.
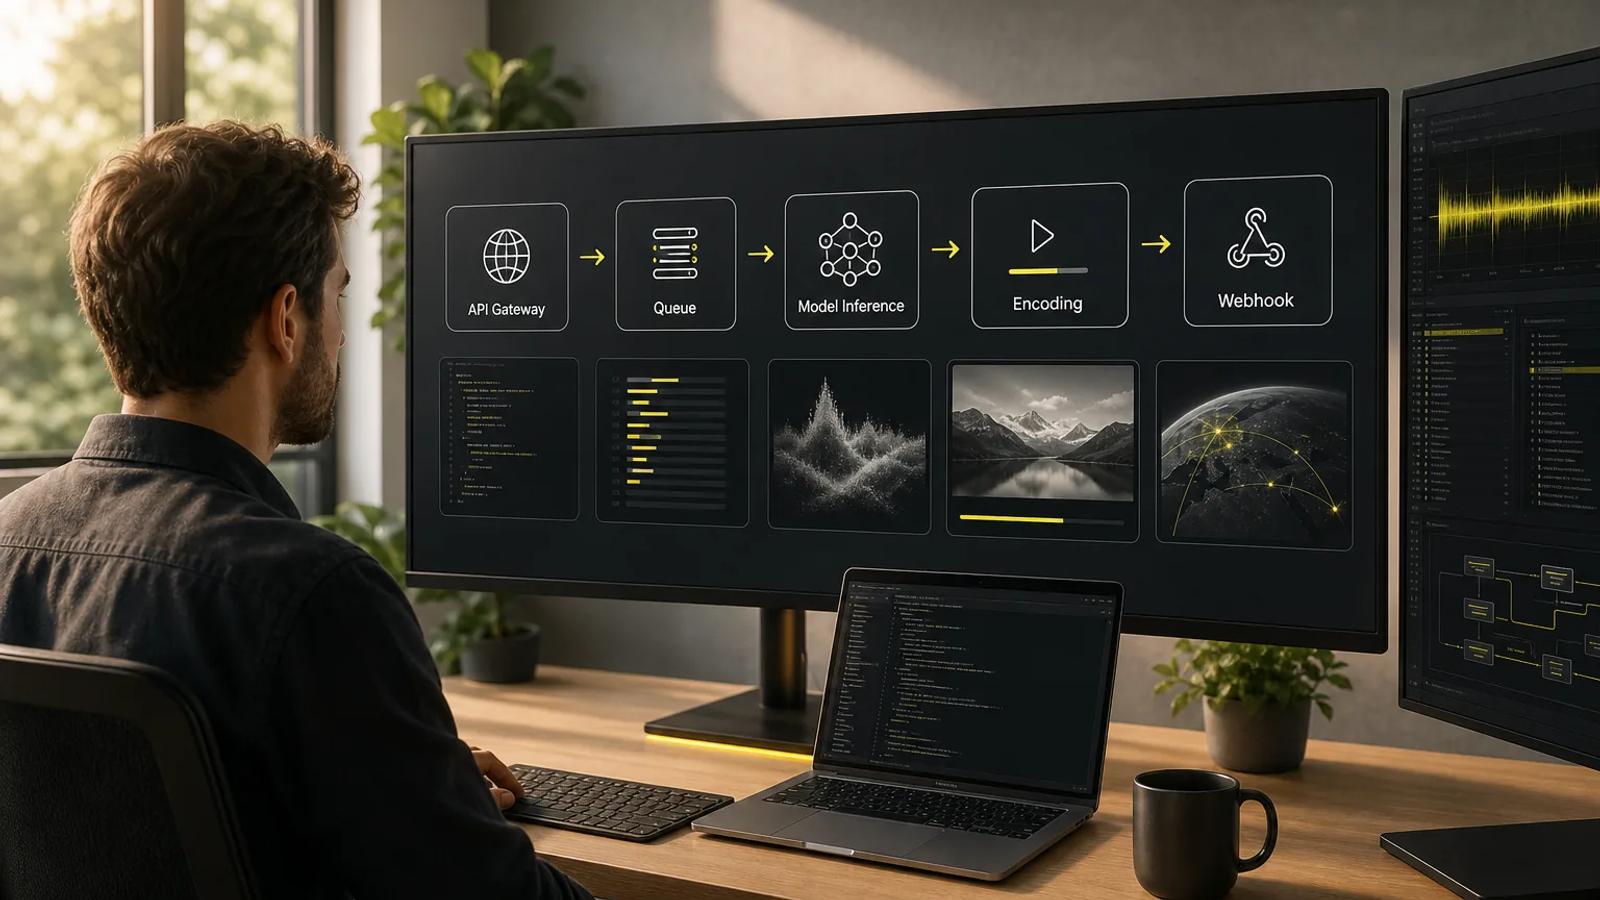
In Apiframe, you send a request to the API with your API key. A generation call returns a job ID with a “queued” status. Your app then checks the job status or waits for an automatic notification (called a webhook), instead of keeping the connection open while the file renders.
curl -X POST https://api.apiframe.ai/v2/images/generate \ -H "X-API-Key: afk_your_api_key" \ -H "Content-Type: application/json" \ -d '{"model":"selected-model","prompt":"a red bicycle on a wet street"}'The request path usually looks like this:
- Your app checks the prompt and input files.
- The gateway (the service between your app and the models) checks your key, credits, limits, and the request format.
- The job enters a queue and receives an ID.
- A router sends it to the selected model.
- The model generates the media.
- The system runs post-processing, checks, encoding, and storage.
- Your app receives a notification or fetches the completed job.
Each of these steps can add to the user’s wait time. A video job might involve handling a reference image, working with individual frames, syncing audio, running a safety check, and encoding, all before it is ready. Our guide on how text-to-video generation works explains why video takes longer. Even an image edit can spend more time moving a file around than actually generating anything new.
This is one reason a unified layer should show status and timestamps for each job. For more on how teams manage several model steps in one workflow, see our guide on migrating from multiple media providers to one API.
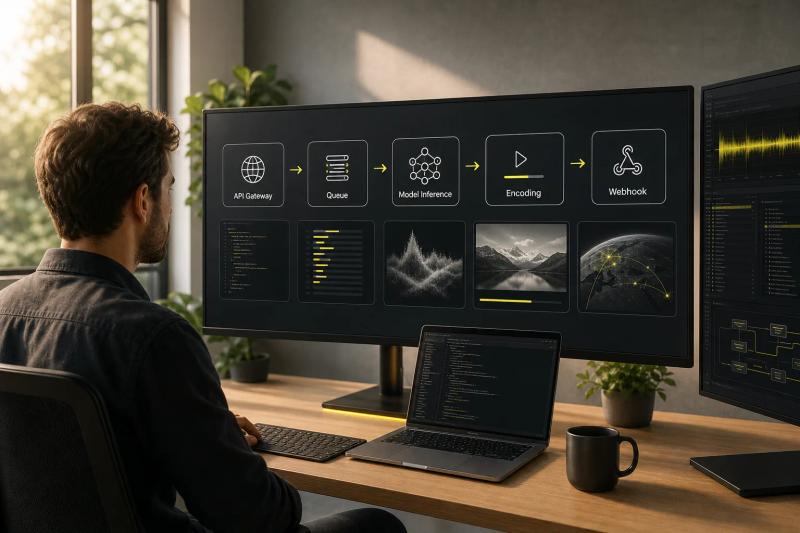
Use clear states in your own database. For example, separate queued, running, post-processing, completed, failed, and expired. Those states give your screen a useful message and stop support staff from guessing from raw provider logs.
For long jobs, never make the browser wait on the original request. Save the job ID, accept a webhook notification, check its signature when supported, and let the user leave the page. Apiframe sends a signature header you can verify, and our guide to setting up webhook callbacks covers how. The workflow can finish even if the browser tab closes.
How to Benchmark Unified Media API Performance
A fair performance test keeps the workload the same while only the provider changes. Use the same region, type of prompt, output size, reference files, timeout, and retry settings for every run.
Start with a small, varied test set instead of a single showcase example. Include both easy and hard prompts. Add a “cold” request after a period of inactivity, then repeat requests right after. Test each media type using the output size your product will actually use.
| Test case | What to hold still | What to record | Decision it supports |
|---|---|---|---|
| Image draft | Size, model, prompt class | Queue, generation, delivery | Interactive editor fit |
| Video clip | Duration, motion mode, inputs | Accepted clip time and P95 | Foreground or background workflow |
| Music track | Length, model, prompt type | Job completion and failure rate | Batch or live product fit |
| Load test | Payload and request rate | Queue growth and rejection rate | Concurrency planning |
| Retry test | Timeout and idempotency rule | Duplicate jobs and added cost | Safe failure handling |
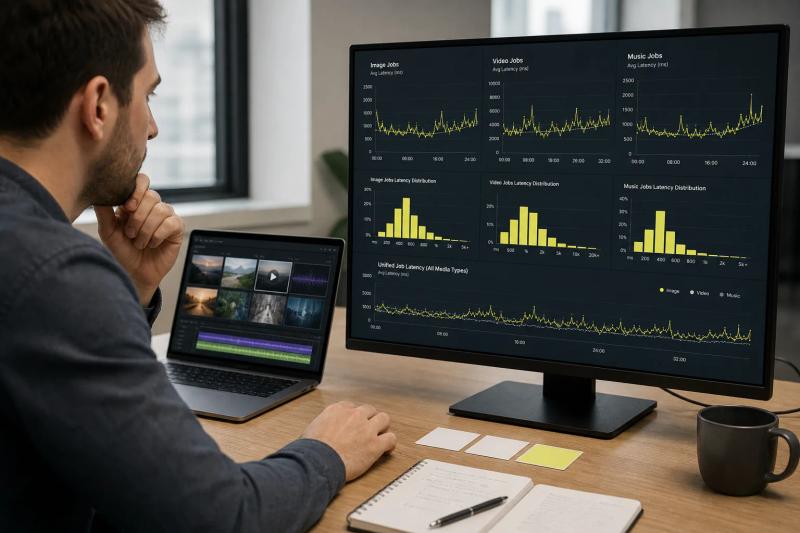
Record P50, P95, and P99. These are the standard way to describe a spread of results instead of a single average. P50 is the typical request, where half finish faster. P95 means 95% of requests finish faster than that time, and it shows the slower edge that affects many users. P99 exposes the painful tail that can break a launch or batch deadline.
Also log the request time, the time it was accepted, the time it started, the time it finished, the time the file was ready, the model version, the region, the file size, and the attempt number. Note the date of the test too, since a model update can change results without any change on your end.
Published market data is itself a warning sign about how little gets shared. In one sample of eight media APIs, only three published image speed at all, and none published video speed, music speed, or maximum concurrent jobs. That makes starter credits more useful than just a way to save money. They let you run your own test set before committing to a paid plan.
Apiframe offers 100 starter credits after a quick phone check or a one-time $1 payment, so you can test your actual prompts, sizes, notification setup, and traffic pattern before you commit. Do not replace your own test with a claim from a homepage. Our comparison of AI media APIs with free trials shows what else you can test for free.
When comparing models, make sure you are comparing similar work. Check the Apiframe model list to find the image, video, or music option that fits your use case before you start testing. A quick image draft is not a fair comparison against a high-resolution edit, and a five-second video made from a reference image is a different workload than one made purely from text. What matters is whether the output is actually usable, not just whether it came back. Our guide on how to test the quality of AI-generated video shows how to judge that.
Pro tip: Save raw job events next to your dashboard averages. When a P95 spike appears, you can see whether queue wait or delivery caused it.
Usable Ways to Reduce AI Media Generation Delays
Reduce delay by cutting avoidable work before you change providers. The largest gains often come from request size, queue behavior, and delivery design.
Choose the right output workload
Use a smaller image size for early drafts, when the user just needs to check the layout. Generate the full-size version after they approve it. For video, use short previews and only render the full clip once the user confirms the scene. Test output settings against the actual task instead of assuming the highest resolution is always right. Our AI video generation API guide and AI image API guide walk through typical settings for each media type. If you build for phones, see our list of the best unified APIs for low-latency mobile image generation.
Keep the request path short
Upload reference files before the user submits a generation request. Reuse existing upload sessions when it is safe to do so, and avoid routing the same file through several services before the model even sees it.
Cache things that repeat, like prompt templates, style presets, model details, and preview thumbnails. Just do not cache a result the user expects to be freshly generated. For example, a product catalog workflow can reuse the same product photo and only regenerate the parts that changed.
Use async jobs and webhooks
Submit the job, return control to the client, and let the notification update your database. When a webhook is not possible, check status at gradually longer intervals instead of every few seconds (a “backoff schedule”). Do not check every second across thousands of jobs, since that adds load without making the model finish sooner.
Set a client timeout around request acceptance, not full media completion. Then set a separate product deadline for the finished asset. Those are different failures and need different messages.
Make retries safe
Retry network failures with a limit. Give each logical generation a unique ID that prevents it from accidentally starting twice, known as an idempotency key, when the API supports one. Apiframe supports an Idempotency-Key header for this. Otherwise, a browser timeout can leave the first job running while the retry starts a second paid generation.
Fallbacks (switching to a backup model) can reduce failure time, but they can also change style, cost, dimensions, or quality. Write a routing rule for each type of job. A low-resolution draft may use one model, while a final ad asset needs another.
Apiframe keeps model selection behind one request format, so switching the model value does not require a new sign-in setup. You still need to benchmark each route. A simpler swap reduces code work, not model-specific wait time.
Reliability, SLOs, and Performance Trade-Offs
A useful service level objective (SLO), which is the target your team holds itself to, works on two levels for a unified media API. The API-level target covers acceptance and delivery. The product-level target covers how long it takes before a user can actually use the finished file.
For an image editor, your product target might track what share of approved drafts are ready within a set window. For video, it might track what share of jobs are delivered before a scheduled posting time. Pick a window that fits the workflow. A daily average can easily hide a queue backup during a busy launch.
Track these measures separately:
- Accepted request rate
- Completion rate
- Accepted-output latency at P50, P95, and P99
- Notification delivery delay
- Retry rate and duplicate-job rate
- Queue depth and concurrency use
- Credit use per accepted asset
From there, set an error budget, meaning how many missed targets you will tolerate before pausing other work to fix the problem. If too many video jobs miss their deadline, pause new feature work until you have fixed the queue, retry logic, or routing. Do not hide misses by only counting successful requests. Failed jobs and abandoned sessions are part of the real user experience.
Speed and quality can pull against each other. A smaller model or lower resolution may finish sooner, but a lower-quality result can push the user to try again. Measure time-to-accepted-output and cost-per-accepted-output, not just raw generation time.
Concurrency, meaning how many jobs can run at the same time, deserves special care. More workers can reduce queue wait until the upstream model or your plan limit becomes the bottleneck. A public speed figure without a concurrency condition tells you little about a busy product.
Apiframe’s paid plans set how many jobs can run at once: 5 on Basic, 12 on Pro, 50 on Growth, and 100 on Scale. Check that limit against your own queue design before launch. Even a plan with plenty of monthly credits can slow down during a traffic spike if its job limit is too low. Our guide to enterprise unified media API features covers what to look for at larger scale.
Keep a dated benchmark report for every important model route. Include the prompt set, request format, output rules, region, traffic level, retry policy, and model version. Review it after a model update or a change in user flow. For more on securing that setup as it scales, see our AI media API security best practices. If you are still choosing a provider, our guide on how to choose an AI media API can help.
FAQ
What is latency in a unified media API?
Latency is the time between a user’s request and a usable, finished file. In a unified media API, this breaks down into acceptance, queue wait, model generation, post-processing, and delivery. The first response can come back quickly while the image, video, or music file is still being generated.
How can AI image and video API speed be measured?
Measure each job from the moment it is submitted through to when the file is delivered, and record the queue time and generation time separately. Run the same request several times and record the P50, P95, and P99 results. It is also worth tracking whether the output passed your checks the first time or needed an immediate retry.
Does a unified API add latency?
A unified API can add a small routing or queue step, but this is usually a minor part of the total time. In exchange, you get a shared job format, notification setup, and billing system. It is worth testing that added step alongside model time, storage time, and queue wait, instead of assuming it is a major factor.
Why are video generation APIs slower than image APIs?
Video takes longer because the system needs to produce many connected frames, and it often has to handle motion, reference images, audio, safety checks, and encoding. A five-second video clip is not the same as five seconds of processing. Always compare clips with the same length, mode, and input files.
What should an AI media API SLO include?
An AI media API service level objective should include acceptance rate, completion rate, accepted-output latency, notification delay, and failure rate. Add measurements for concurrent jobs and queue depth so you can explain any missed targets. Keep your infrastructure targets separate from the product target that reflects when a user can actually use the finished asset.
Conclusion
Use accepted-output latency as your main product measurement, and support it with data on queue wait, generation time, delivery, and retries. Start with Apiframe’s starter credits, run your own fixed test set across the models you plan to use, and set your targets based on those real results. When you are ready to start building, our Getting Started with Apiframe guide walks through your first API call.